SRE Consulting Services in Oman

Losing sleep over outages that keep repeating, or deployments that never feel safe to ship? Lyqa Tech Ventures designs, implements and supports Site Reliability Engineering practices for businesses across Oman – from a single customer-facing application to a multi-service cloud platform running around the clock.

We are an Omani-owned technology company delivering IT solutions, ELV services, cybersecurity and AI services across Muscat, Sohar, Salalah and Duqm. Your SRE engagement is handled by the same team that already understands your infrastructure, security posture and network – not a disconnected specialist brought in for one project.

When a Business in Oman Needs SRE Consulting

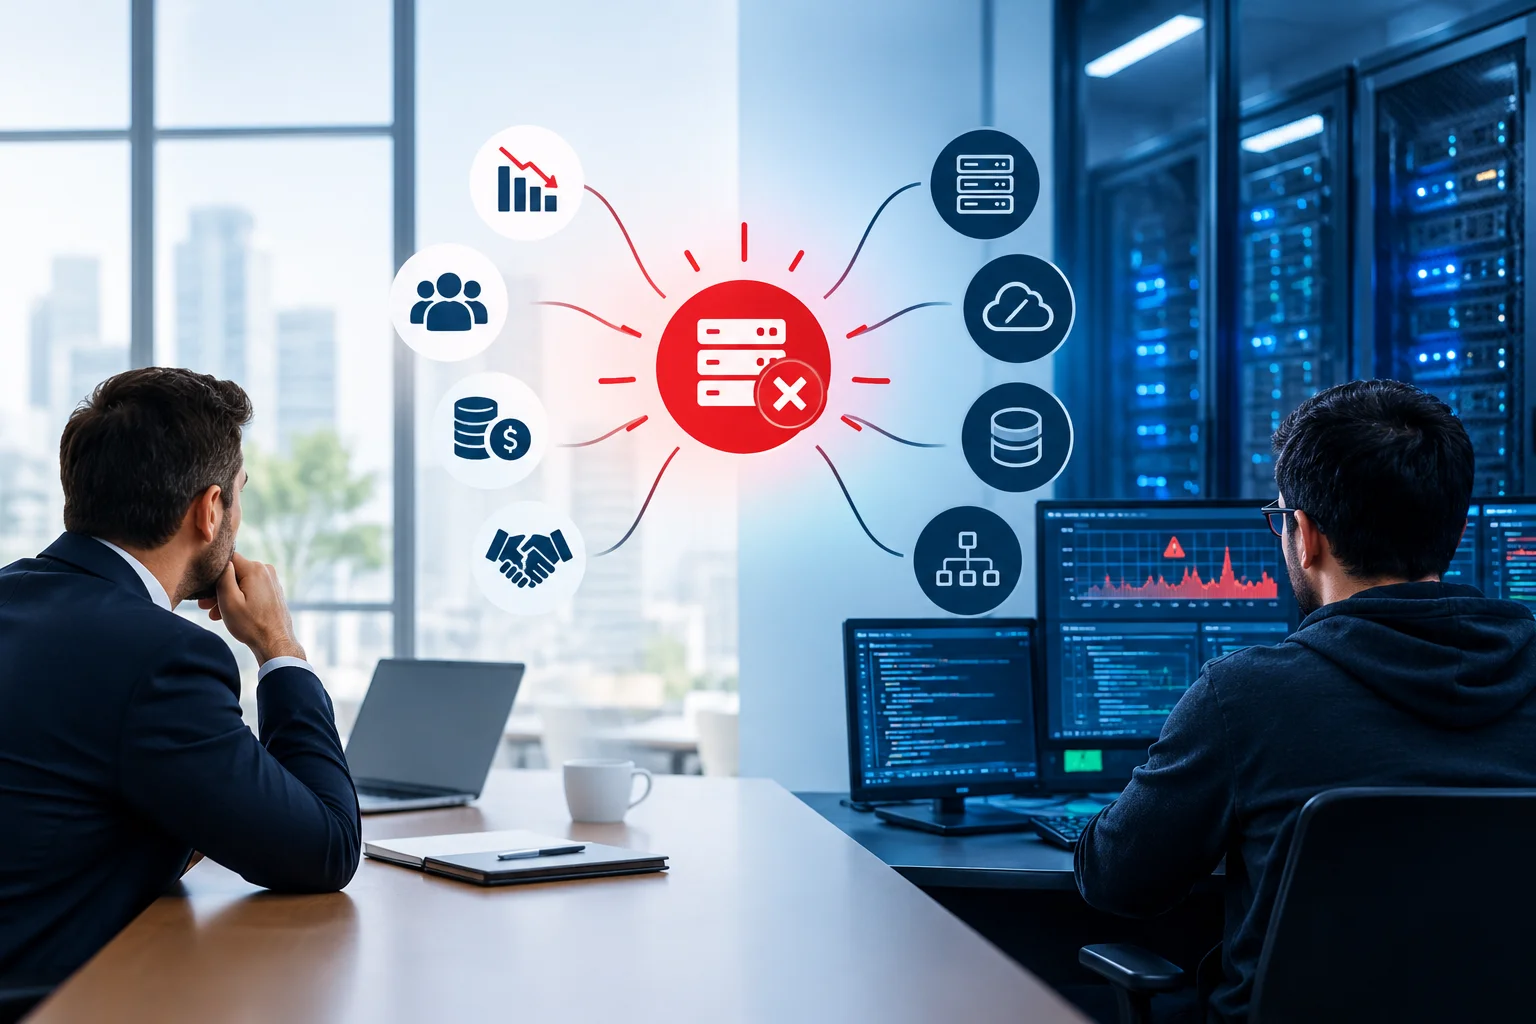
Downtime Is a Business Problem Before It's a Technical One

An outage rarely stays a technical issue for long. A checkout page that goes down during a promotion, a booking system that fails during peak season, or a client portal that's slow every Monday morning - each of these becomes a customer service problem, a support-ticket problem and eventually a revenue problem. SRE consulting exists to catch that chain of events earlier, at the infrastructure level, before it reaches your customers.

Reliable" Should Actually Mean for Your Systems - SRE Consulting

What "Reliable" Should Actually Mean for Your Systems

Most teams describe reliability in vague terms - "it's usually fine" or "we had a bad week." SRE replaces that with numbers: Service Level Objectives (SLOs) that state what reliability target a service should hit, Service Level Indicators (SLIs) that measure it, and an error budget that tells you how much unreliability is acceptable before you stop shipping new features and fix stability instead. This framework, developed and popularised by Google's SRE practice and now standard across the industry, gives everyone - engineering, management and customers - the same definition of "working."

Where Reliability Initiatives Usually Stall

In our experience, it's rarely the monitoring dashboard that's missing. It's what sits around it: alerts with no owner, incidents that get patched but never root-caused, automation scripts nobody trusts enough to run unattended, and on-call rotations that exist on paper but not in practice. An SRE consulting engagement is built to fix that gap, not just add another tool to the stack.

Reliability Initiatives Usually Stall - SRE Consulting

SRE Consulting Services We Deliver

Reliability & SLO Design

We work with your team to define SLOs and SLIs tied to what actually matters to your business - transaction success rate, page load time, API latency - and set an error budget policy that gives engineering a clear, agreed threshold for when to prioritise stability over new features.

Observability & Monitoring Implementation

Logs, metrics and traces are brought into a single view so your team can see a problem forming rather than learning about it from a support ticket. We configure alerting thresholds that reflect your SLOs, so alerts mean something instead of arriving constantly and being ignored.

Incident Response & On-Call Engineering

We build the incident process itself: escalation paths, on-call scheduling, severity definitions and a blameless post-incident review format focused on fixing the underlying cause rather than assigning blame.

Automation & Toil Reduction

Repetitive manual work - deployments, scaling, routine restarts, certificate renewals - is identified and automated in stages, starting with the tasks that carry the highest risk of human error.

DevOps–SRE Process Integration

For teams already running CI/CD pipelines, we integrate reliability gates and rollback safety into the existing deployment process rather than introducing a parallel workflow.

Cloud & Hybrid Infrastructure Reliability

We review your cloud or hybrid architecture for single points of failure, unmanaged scaling limits and recovery gaps, and design for resilience appropriate to your actual traffic and growth, not a generic enterprise template.

Specialized Reliability Scenarios

Not every system carries the same risk profile:

High-transaction platforms - e-commerce, payments and booking systems - where a short outage during peak hours has an immediate revenue impact.

Regulated or sensitive data environments, where reliability work has to stay aligned with your existing security and compliance controls rather than work around them.

Multi-region or high-availability architectures, where failover and data consistency need deliberate design, not an assumption that the cloud provider handles it automatically.

Legacy systems being modernized, where reliability practices have to be introduced gradually alongside a migration, not applied all at once to infrastructure that predates the tooling.

API-dependent platforms, where a third-party outage can look identical to your own - and your monitoring needs to tell the difference quickly.

SITE RELIABILITY ENGINEERING

Reactive Operations vs. SRE-Led Operations

A straight comparison to show what changes when reliability becomes a discipline rather than a reaction.

Area Reactive Operations SRE-Led Operations
How issues are found
Customers or support tickets report them Monitoring and SLO alerts flag them early
Definition of "reliable"
Informal, varies by person Explicit SLOs and SLIs everyone agrees on
Root cause handling
Symptom is patched, issue often repeats Root cause investigated, fix prevents recurrence
Deployments
Manual, treated as risky Automated with rollback safety built in
On-call
Ad hoc, whoever is available Structured rotation with clear escalation
+ Decision to slow down feature work
Rarely made until after a major incident Guided by error budget before it's exhausted
Operational cost over time
Rises as incidents repeat Falls as toil is automated away

Who We Work with Across Oman

Banks and financial services AI governance

Retail & facilities operators

E-commerce and Retail Platforms

Reliability engineering focused on checkout availability, payment gateway monitoring and traffic spikes during sales periods and seasonal peaks.
Financial and Professional Services

Incident processes and monitoring designed to work alongside existing security and audit requirements, without creating conflicting controls.
Hospitality

Hospitality and Travel Platforms

Reliability for booking engines and guest-facing systems where downtime during peak travel periods is highly visible and costly.
Government and Public Sector Digital Services

Observability and incident response built for services with defined uptime expectations and formal reporting requirements.
Logistics & trading

Logistics and Supply Chain Operators

Monitoring and automation for tracking, dispatch and warehouse systems where an outage disrupts physical operations, not just a webpage.
How a Lyqa Tech SRE Engagement Runs

Discovery and Assessment

We review your current infrastructure, incident history, monitoring setup and deployment process to see where reliability is actually breaking down.

Reliability Roadmap and SLO Definition

We agree SLOs, SLIs and an error budget policy, then prioritise the fixes that will reduce incidents fastest.

Monitoring and Automation Build

We implement observability tooling and automate the highest-risk manual tasks, working alongside your existing team.

Incident Process and on-call Setup

We put escalation paths, severity levels and a post-incident review format in place, and train your team to run them.

Validation and Handover

We test the setup against real conditions, document everything, and either hand it over to your team or continue as an ongoing SRE managed service.

24/7 Support

Scheduled review and refinement as your data, systems and business needs change.

Request a Reliability Assessment

Tell us what's currently running, how it's monitored today, and what's been causing the most disruption - and we'll tell you what an SRE engagement should actually focus on before we quote anything.

What Drives the Cost of SRE Consulting in Oman

We don't publish fixed packages, because the right scope depends on your systems. The variables that actually move the price:

Number of services and applications in scope, and how they depend on each other.

Current state of monitoring and automation - starting from nothing costs more than refining an existing setup.

Cloud, on-premises or hybrid infrastructure, and how many environments need coverage.

Whether the engagement is a one-time setup with handover, or an ongoing managed SRE service.

Integration requirements with existing CI/CD, ticketing and communication tools.

Team size and how much hands-on training or documentation your internal staff need to run things independently.

Cost of SRE Consulting in Oman

Designing Reliability for Omani Operating Conditions

Regional Infrastructure

Uptime Commitments

Scalable Reliability

Proactive Monitoring

Why Choose Lyqa Tech Ventures for SRE Consulting

Omani-owned and SME-registered, with the local standing that matters for government and enterprise engagements.

Reliability work is delivered alongside our existing IT infrastructure, cybersecurity and AI services, so monitoring, security and automation are designed together rather than negotiated between separate vendors.

Vendor-agnostic - we recommend monitoring, automation and cloud tooling based on what your systems need, not what we're contracted to resell.

One accountable team from assessment through to ongoing support, so responsibility for reliability doesn't sit between multiple providers.

Service areas

We deliver SRE consulting and support to businesses across Muscat (head office, Bousher), Sohar, Salalah and Duqm, including port, free zone and SEZAD-based operations.

Request a Reliability Assessment

Tell us what's currently running, how it's monitored today, and what's been causing the most disruption - and we'll tell you what an SRE engagement should actually focus on before we quote anything.

Frequently Asked Questions

Is SRE consulting only useful for large tech companies?

No. SRE practices scale down well – a small team running a single customer-facing application benefits from clear SLOs and basic automation just as much as a large platform, often with a lighter setup.

IT support typically reacts to issues as they’re reported. SRE builds the monitoring, automation and process that reduce how often issues happen in the first place, and makes recovery faster when they do.

Yes. We assess and build around your current stack rather than requiring a migration to specific tools, and we integrate with the CI/CD and monitoring tools you already use where practical.

No. Reliability work is implemented in stages alongside your normal release schedule, so production systems and ongoing development aren’t put on hold during the engagement.

That’s a normal starting point. Assessment and monitoring setup are usually the first phase of the engagement, and SLOs are defined once there’s real data to base them on.

That’s a normal starting point. Assessment and monitoring setup are usually the first phase of the engagement, and SLOs are defined once there’s real data to base them on.