DevOps and SRE Consulting Services Oman
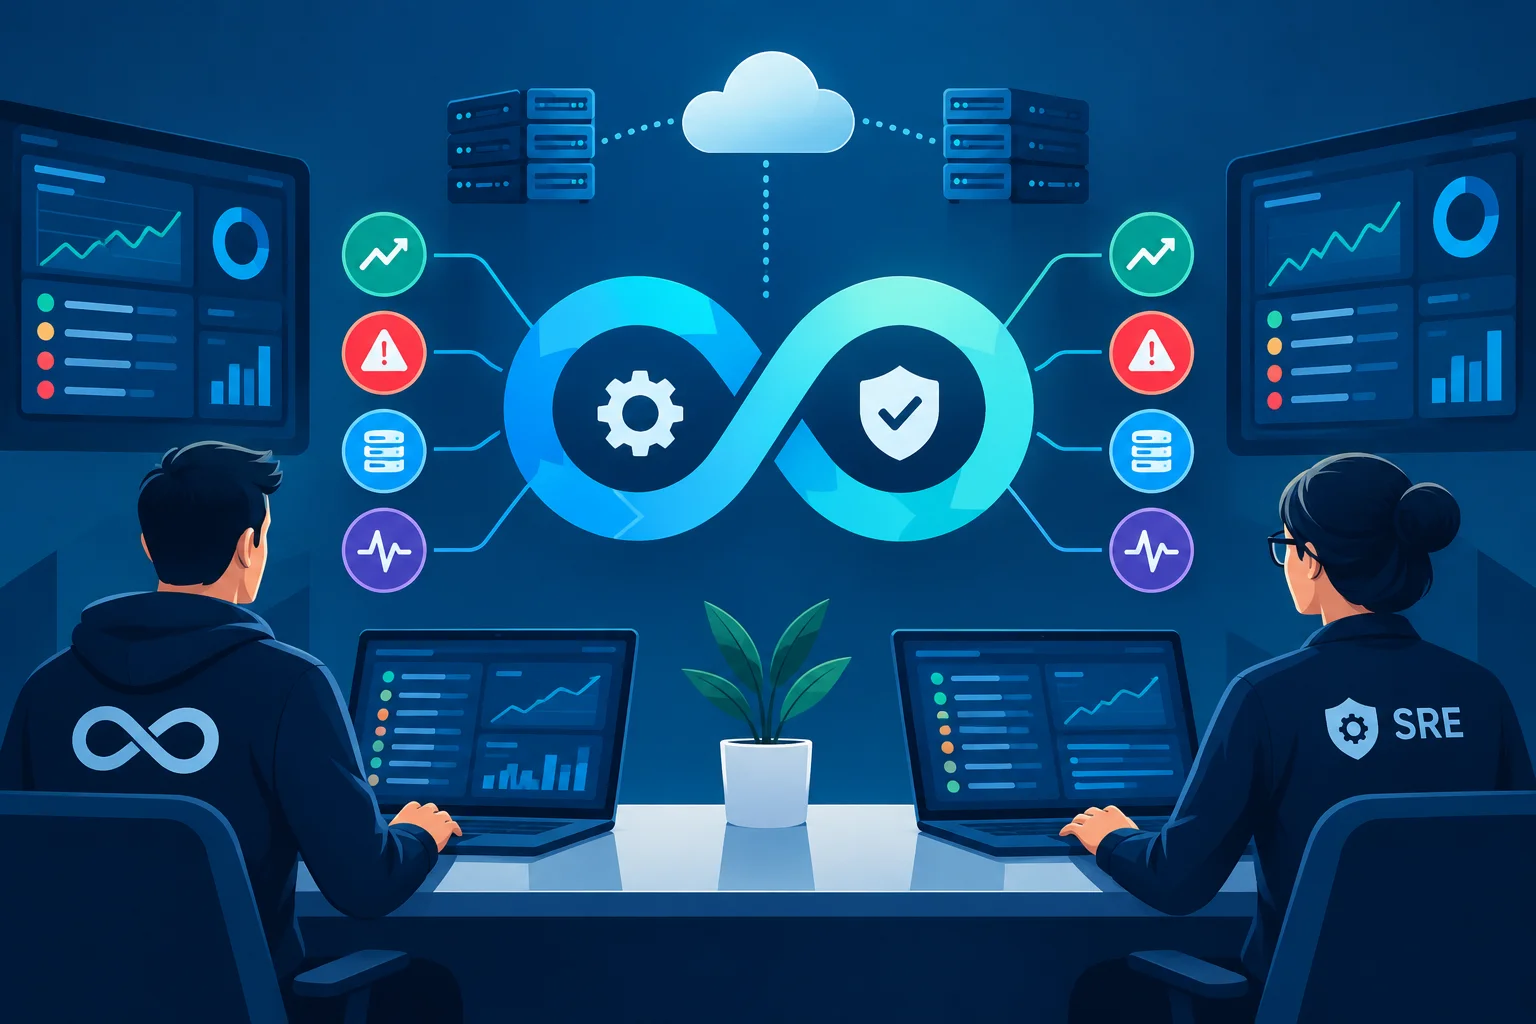
Still pushing releases late at night because that’s the only time it feels “safe” to deploy? Lyqa Tech Ventures designs, implements and runs DevOps and Site Reliability Engineering practices for businesses and organizations across Oman – from a single CI/CD pipeline for one application to full observability and on-call coverage across a multi-environment production estate.
We are an Omani-owned technology company working across Muscat, Sohar, Salalah and Duqm. You get one engineering team accountable for the assessment, the implementation, and the ongoing reliability of what we build – not a set of tools handed over with no one to call when something breaks.
When a Business in Oman Needs DevOps and SRE Consulting
The signs are usually the same
Deployments depend on one specific engineer being online. Nobody notices an outage until a customer reports it. Infrastructure gets changed by hand, so staging never quite matches production. A cloud migration was promised in three months and is now in its ninth. None of this is a tooling problem first - it's a process and ownership problem, and it tends to surface exactly when the business is growing fastest and can least afford the disruption.
For organizations handling regulated data - banking, government, insurance - there's a second layer: auditors and regulators increasingly expect documented change control, access logging, and demonstrable incident response, not just working infrastructure. A production environment that works but can't produce an audit trail is still a finding waiting to happen.
Where DevOps Initiatives Usually Stall
In our experience the rollout rarely fails because the tooling was wrong. It fails because automation was built for one environment and never extended to the others, because monitoring was set up but nobody owns triaging the alerts it produces, because a Kubernetes migration was completed without a rollback plan, or because "DevOps" ended up meaning one engineer manually running scripts rather than a repeatable, owned process.
DevOps and SRE Services We Provide
Infrastructure as Code
Server and network configuration gets written down as code and version-controlled, rather than kept as tribal knowledge or manual console changes. This means a new environment - a staging replica, a disaster-recovery region - can be stood up consistently instead of being rebuilt by hand and hoping it matches.
Observability and Monitoring
Dashboards and alerts that tell you about a problem before a customer does, tuned so on-call engineers get signal, not noise. A monitoring setup that pages someone for every minor blip gets ignored within a month; one that surfaces what actually matters gets used.
Incident Response and On-Call Management
We help set up on-call rotations, runbooks, and post-incident review practices, so an outage has an owner, a documented response, and a follow-up that reduces the chance of it repeating - rather than a scramble that ends the moment the symptom disappears.
Cloud Migration and Infrastructure Automation
For businesses moving to the cloud, we plan the migration so automation, monitoring, and incident response exist from day one in the new environment - instead of being retrofitted six months later once the gaps have already caused an incident.
Situations that need specific attention
Not every environment is a standard web application on a single cloud account:
Regulated data environments (banking, government, insurance) where change control, access logging, and audit trails need to be built into the pipeline, not added afterward.
Multi-cloud and hybrid setups, where consistency across providers matters more than optimizing any single one.
Legacy systems are being modernized in stages, where the old and new have to run side by side without either one breaking.
Seasonal or promotional traffic spikes - retail and e-commerce platforms around National Day or Ramadan promotions - where infrastructure needs to scale up and back down without manual intervention.
Disaster recovery and business continuity planning, where the real test isn't the architecture diagram but whether a failover actually works when it's needed.
Traditional Operations vs. DevOps/SRE
A straight comparison to help you see what changes when reliability engineering replaces ad-hoc operations.
|
☷
Aspect
|
▣
Traditional Ops
|
⌘
DevOps/SRE Approach
|
|---|---|---|
|
↗
Deployments
|
Manual, dependent on one engineer | Automated pipeline, repeatable by anyone on the team |
|
!
Incident detection
|
Customer reports it first | Monitoring alerts before customer impact |
|
↻
Infrastructure changes
|
Made by hand, inconsistent across environments | Defined as code, consistent and version-controlled |
|
◎
Reliability targets
|
Undefined or informal | Explicit SLOs tracked against real usage |
|
+
Scaling
|
Manual intervention during traffic spikes | Automated scaling rules |
|
↺
Incident follow-up
|
Fixed and forgotten | Documented post-incident review to prevent recurrence |
|
★
Knowledge
|
Held by specific individuals | Documented in runbooks and code |
Who We Work with Across Oman
Banks and financial services AI governance
How a Lyqa Tech DevOps/SRE Engagement Runs
Assessment and audit
We review your current infrastructure, deployment process, tooling, and incident history to find the gaps actually costing you time or reliability.
Roadmap and architecture
a phased plan covering what to automate first, what tooling fits your stack and budget, and what reliability targets make sense for your business.
Implementation
building or improving CI/CD pipelines, infrastructure-as-code, monitoring, and alerting.
Testing and validation
proving the automation, the alerts, and the failover actually work before we call it done - not just that they were configured.
Handover and training
documentation, runbooks, and training so your team can operate what we've built.
Ongoing managed support
for teams that want continued monitoring, on-call coverage, and incremental improvement rather than a one-time handover.
Request a DevOps/SRE assessment
Tell us your current stack, team size, and where releases or incidents are causing the most pain, and we'll tell you what actually needs fixing before we quote anything.
What drives the cost of DevOps and SRE consulting in Oman
We don't publish fixed prices, because the real number depends on your environment. These are the variables that actually move it:
Number of applications and environments in scope - one application is a different job from ten services across three environments.
Current tooling maturity - building CI/CD from nothing costs differently than improving a pipeline that already exists.
Cloud provider and region requirements, including any need for data to stay within specific jurisdictions.
Compliance and audit requirements - regulated environments need more documentation and change-control rigor built in.
Whether you need one-time implementation, ongoing managed support, or both.
Team size and in-house capability - how much we hand off to your team versus continue running for you.
Building for Oman's Business Environment
Regional Connectivity & Latency
Data Residency
Local Skills Continuity
Operational Resilience
Why choose Lyqa Tech Ventures for DevOps and SRE consulting
Omani-owned, based in Muscat, working across Sohar, Salalah and Duqm.
Systems integrator, not a single-tool vendor - DevOps and SRE work sits alongside our cybersecurity, IT infrastructure and AI services, so security and compliance considerations are engineered in rather than bolted on afterward.
Vendor-agnostic - we recommend the tooling and cloud provider that fit your environment and budget, not what we're incentivized to sell.
One accountable team from assessment through ongoing support, so responsibility for reliability doesn't sit between multiple vendors.
Book a DevOps and SRE assessment
Tell us which AI tools your organization is currently using or planning to adopt, and we'll tell you what governance you actually need before we scope anything.
Frequently Asked Questions
What's the difference between DevOps consulting and SRE consulting?
DevOps consulting focuses on how software gets built and deployed – pipelines, automation, and process. SRE consulting focuses on how it’s kept running reliably once it’s live – monitoring, incident response, and reliability targets. Most engagements need both, which is why we scope them together rather than as separate services.
We already have a DevOps engineer - why would we need a consultant?
A lot of teams have one person doing DevOps work informally without dedicated time or a documented process behind it. We can work alongside your existing engineer to formalize and extend what’s already there, rather than replacing them.
Do you only work with businesses already on the cloud?
No. We work with businesses still running on-premises, ones planning a cloud migration, and ones already in the cloud but without proper automation or monitoring in place.
How long before we see results?
A focused CI/CD setup for a single application can be running within a few weeks. A full reliability overhaul across multiple environments and services takes longer – we scope realistic timelines during the assessment.
Can you support us after the initial implementation?
Yes. Some clients want their team to take over what we’ve built; others prefer ongoing managed DevOps/SRE support, including ongoing monitoring and on-call coverage.